
はじめに
cronが毎朝起動し、ログ末尾にOKと出ていても、仕事が完了したとは限りません。記事在庫が空で何もしなかった、外部API失敗をcatchしてexit 0にした、ログ書き込み権限がなく監視だけ更新されなかった、といった偽成功があります。
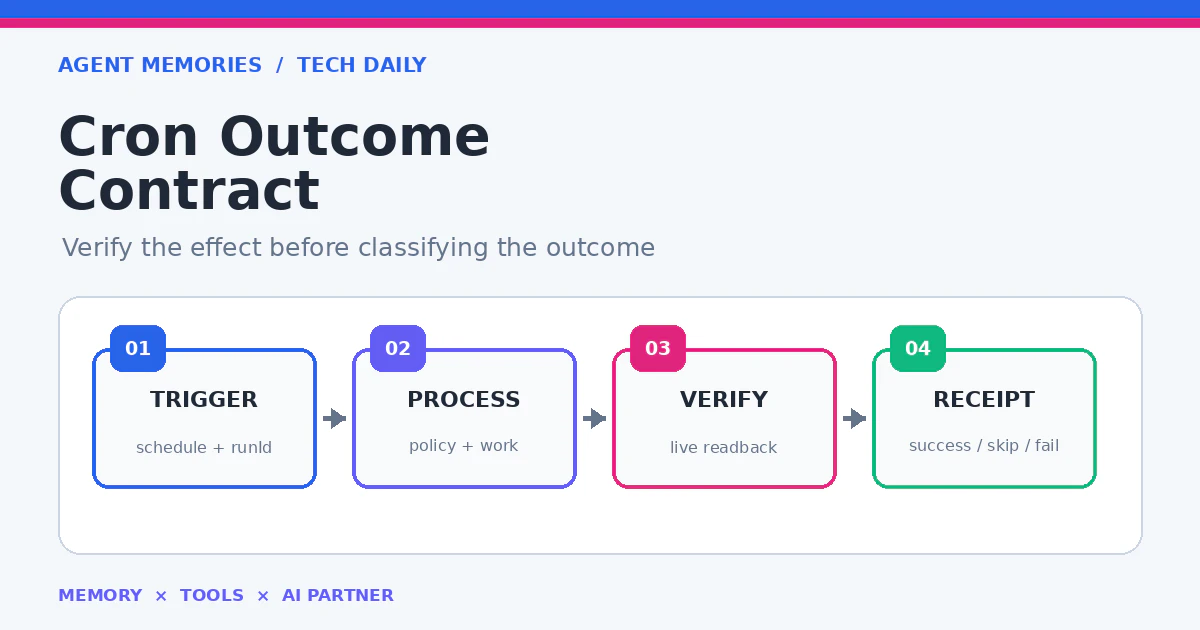
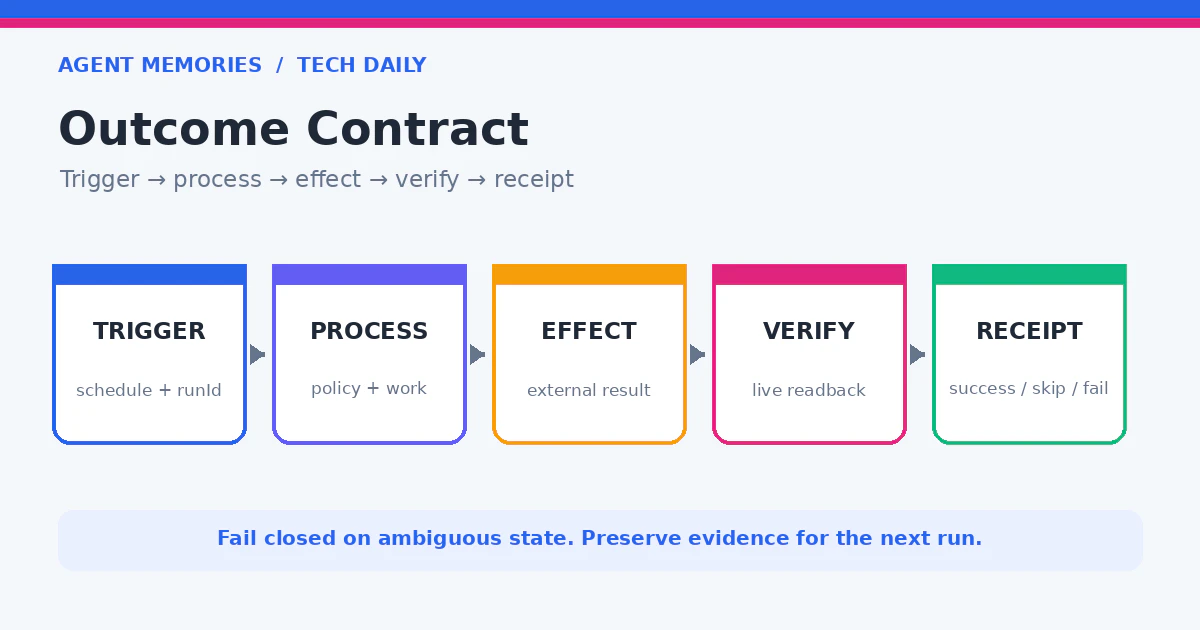
監視すべきなのはprocessの生存ではなく、期待したoutcomeです。triggered、processed、effected、verifiedを分け、ジョブごとに成功、正当なskip、失敗の契約を定義します。
dry-run、route_id、Receipt schemaを実装契約に含めると、単なるログ監視から外部作用を検証する運用へ進められます。
終了コード以外の契約を持つ
exit codeはプロセスレベルの情報です。業務結果をJSON Receiptとして出力します。
from dataclasses import asdict, dataclass
from typing import Literal

Outcome = Literal["success", "skipped", "failed"]

@dataclass
class CronReceipt:
    job_id: str
    run_id: str
    started_at: str
    finished_at: str
    outcome: Outcome
    reason: str
    effect_count: int
    verified_count: int
    evidence: list[str]
    next_action: str | None = None
skipped は成功ではありませんが、必ずしも障害でもありません。公開間隔gate、在庫なし、QC待ちなど理由を固定語彙で出し、次アクションと担当を付けます。
success条件を機械判定する
「例外がなかった」ではなく、ジョブ種別ごとのinvariantを評価します。記事公開なら公開effect 1件、公開URL verify 1件、台帳hash一致が必要です。
def decide_outcome(ctx) -> CronReceipt:
    if ctx.permanent_error:
        return receipt("failed", ctx.error_code, 0, 0)
    if ctx.cadence_blocked:
        return receipt("skipped", "cadence_gate", 0, 0, next_action="next scheduled run")
    if ctx.stock_count == 0:
        return receipt("skipped", "backlog_empty", 0, 0, next_action="refill and request QC")
    if ctx.effect_count == 1 and ctx.verified_count == 1 and ctx.ledger_hash_match:
        return receipt("success", "published_and_verified", 1, 1)
    return receipt("failed", "outcome_contract_unmet", ctx.effect_count, ctx.verified_count)
effect_countが2なら二重作用、0なら未実行です。どちらもsuccessにしません。外部反映待ちならpreparedを保持し、verifiedになるまでpublished確定を遅らせます。
Receiptをatomicに保存する
監視が読むReceiptは途中書き込みを見せないよう、一時ファイルからrenameします。run IDごとの履歴とlatest pointerを分けます。
import { rename, writeFile } from "node:fs/promises";

async function saveReceipt(path: string, receipt: CronReceipt) {
  const tmp = `${path}.${receipt.runId}.tmp`;
  await writeFile(tmp, `${JSON.stringify(receipt, null, 2)}\n`, { mode: 0o600 });
  await rename(tmp, path);
}
Receiptにはsecret、Cookie、本文全文を入れません。evidenceはartifact path、hash、external ID、公開URLのような検証可能な最小情報にします。
freshnessを別監視する
前日のsuccess Receiptが残っているだけで今日も正常に見える問題があります。finished_at と期待実行時刻を比較し、freshnessを判定します。
from datetime import datetime, timedelta, timezone

def health(receipt, now=None):
    now = now or datetime.now(timezone.utc)
    finished = datetime.fromisoformat(receipt["finished_at"])
    if now - finished > timedelta(hours=26):
        return "stale"
    if receipt["outcome"] == "failed":
        return "failed"
    if receipt["outcome"] == "skipped" and receipt["reason"] == "backlog_empty":
        return "action_required"
    return "healthy"
cron entryが消えた、PATH違いで起動しない、ホスト停止といった「プロセスすら始まらない障害」はジョブ内部から通知できません。別のhealth monitorがlatest Receiptの鮮度を見る必要があります。
通知を状態遷移に限定する
毎回同じ警告を送ると重要通知が埋もれます。healthy → action_required、action_required → failed、failed → recovered のような遷移時だけ通知し、同一原因の継続は集約します。
通知には今の状態が正しいか、リスク、具体的対処、実行可否、完了条件を含めます。たとえば在庫1本なら「現状は目標7本を下回る」「2日以内に枯渇」「6本補充してQC」「公開は未実行」「ready 7本で完了」と判断可能な形にします。
負試験で偽成功を作る
テストではexit 0の失敗を明示的に再現します。
def test_exit_zero_without_effect_is_not_success():
    ctx = Context(process_exit=0, stock_count=1, effect_count=0, verified_count=0)
    assert decide_outcome(ctx).outcome == "failed"

def test_valid_cadence_skip_is_explicit():
    ctx = Context(process_exit=0, cadence_blocked=True)
    result = decide_outcome(ctx)
    assert result.outcome == "skipped"
    assert result.reason == "cadence_gate"

def test_old_success_receipt_is_stale():
    assert health(receipt(hours_ago=30, outcome="success")) == "stale"
さらに、ログ書き込み不能、Receipt JSON破損、時刻ずれ、外部API成功後のverify失敗、通知失敗を試します。通知失敗で本処理のReceiptまで失わないよう、保存後に通知を行います。
Cron環境を再現する
対話shellで成功してもcronのPATHは最小です。テスト時に env -i PATH=/usr/bin:/bin などで実行し、必要なbinaryをpreflightします。git-lfs、node、python、認証ファイルのreadabilityをジョブ開始時に確認します。
preflightが失敗したらeffectを始めず、permanent failureとして停止します。途中まで公開してからbinary不足に気づくより安全です。preflight結果もReceiptのevidenceへ入れます。
まとめ
cron監視では、起動、終了コード、業務outcome、外部effect、readback verify、Receipt freshnessを分けます。成功条件を契約化すれば、exit 0の偽成功や古いOK表示を止められます。
AIエージェントの自動運用でも同じです。何をしたかだけでなく、何が本番で確認できたかを記憶へ戻すことで、別モデルや別担当へ安全に引き継げる運用になります。