
目次
- 本記事について
- 方針
- Washington D.C.の実際の天気ログを参照し真の温度tを得る
- tempの補正式取得
- humidity = 0 について
- tとhumidity、windspeedからatを算出
- tとatemp
- 正しいatempを算出
- 最後に
本記事について
以下の記事の詳細を別途分けて書いたもの。
題材はKaggleのBike Sharing Demand。
このデータ分析のうち以下の内容を記載している。
正確なatemp値を得たい
- 実施内容抜粋
- tempの補正
- humidity = 0 について
- 真の体感温度をtemp、humidity、windspeedから計算する
- 高温域に於いて:Heat Index -> humidityに依存
- 低温域に於いて:Wind Chill -> windspeedに依存
- atempの補正
- 正確なatemp計算(at_normと命名)
真のatempを算出してレンタル自転車利用者数の予測に使用する。
KaggleのDiscussionでもatempとは何か、及びその算出方法については疑問に挙がっているが、それに対する正確な回答は出ていない。
また、KaggleのOverviewをたどるとデータの出所のページが見つかり、ここでtemp、atempについてnormalizeしているとの記載があるが、この情報は誤った情報であった。
(「値はnormalizeしている」として式が書かれているが、値を0~1にする式。
一方、temp値、atemp値は0以上ではあるが最大値は41度や50度を示している)
https://archive.ics.uci.edu/dataset/275/bike+sharing+dataset
方針
まず、見易いように以下の文字を使う。
| temp | Kaggleで与えられた(気温) |
| atemp | Kaggleで与えられた体感温度 |
| t | 真の温度 |
| at | 真の体感温度 |
方針。
- Washington D.C.の実際の天気ログを参照して、tを得る
- tempとtの分布から、tempの補正式取得
- atempとtの分布から、atの算出式を取得
- tとhumidity、windspeedからatを算出
- atとatempの分布から、atempの補正式取得
- 正しいatempを得る
途中、humidityの外れ値とatempの外れ値についても触れる。
これらは事実上の欠損値なので、それぞれ適切な手法で補完する。
Washington D.C.の実際の天気ログを参照し真の温度tを得る
天気ログの取得
Washington D.C.の2011年1月1日のおおよそ1時間ごと天気予報を手軽に入手できた(ただしデータ取得できていない時刻が散見されるので、完全なデータではない)。
2011年1月1日に於いてwindpeed = 0のデータがいくつかあるので、当該日の天気予報と今回使用しているデータとを見比べる。
KaggleではWebクローリングができないので、Google Chromeのディベロッパーツールで対象となる表のhtmlをコピーしてKaggle上にアップロードし、これをPandasで読み込んで加工した。
データ参照元:https://www.timeanddate.com/weather/usa/washington-dc/historic?month=1&year=2011
このページのやや下のほうに配置されている表。
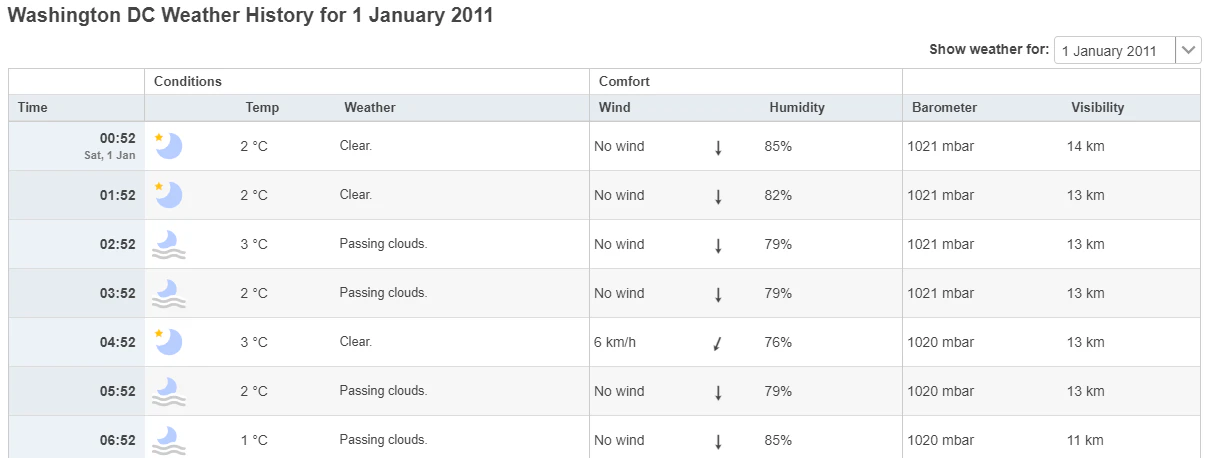
Pandasで取り込んで比較。
#Referring the web page, https://www.timeanddate.com/weather/usa/washington-dc/historic?month=1&year=2011,
#where the weather of Washington D.C.'s weather is recorded.
#The extraction of the table of hourly weather is copied "developer tools" of google chrome as html.
#uploaded the extracted html on Kaggle, the location is as "filename" showing below.

filename = "/kaggle/input/weatherrecord-washington-jan2011/Extraction_Weather_Washington_2011_Jan_timeanddate_com.html"

#read tables from html. returned value will be the list of DataFrames.
list_weather_rep = pd.read_html(filename)

#Now the interested table is list[0], the ast and only DataFrame containd in the html since it is "extracted" selectively.
df_weather_rep = list_weather_rep[0]

#the table has multi-index in columns.
display(df_weather_rep.head(5))

#make it single index(columns) and delete unnecessary columns.
df_weather_rep.columns = [col[1] for col in df_weather_rep.columns]
df_weather_rep=df_weather_rep[["Time","Temp","Weather","Wind","Humidity"]]

#want to diplay some dfs horizontally. "n" means .head()
def display_horizon(*dfs, n=5):
    class HorizontalDisplay:
        def _repr_html_(self):
            template = '<div style="float: left; padding: 5px;">{}</div>'
            return  ''.join(template.format(df.head(n)._repr_html_()) for df in dfs)
    return HorizontalDisplay()

display(display_horizon(df_weather_rep, df_all[["hour","temp","weather","windspeed","humidity"]].iloc[1:,], n=20))
左がwebからの天気予報、右がKaggleで扱うデータ。

※Tempの単位は文字化けしているがセルシウス温度℃である
確認できた情報:
- tempは負の値にならないようにオフセット+スケーリングされている
- windspeed = 0 は確からしい
- windspeedの単位はkm/h
windspeed = 0 は確からしい
windspeed=0の個所は、実際の天気予報でも風速0を示していた。
しかも値として飛んでおり、6km/hの前後でNo wind、となっていたり、No windの次が17km/hだったりする。
windspeed=0なるデータは欠損値を0で代用しているかと予想したが、windspeed=0は確からしい。
風速6(単位はkm/hourと判明)未満は風速0に分類されていると見られる。
windspeed=6以上のデータを確認すると、データの量子化ステップは[0.9983, 1.9966, 2.0033]のいずれかであった。
windspeed=0(0以上6未満は全て0扱い)はほかのデータと比較して量子化ステップがおよそ3倍または6倍となる(ヒストグラムでいうとwindspeed=0のビン幅は他の値の3倍、というイメージ)。
するとwindspeedに関するヒストグラムのwindspeed=0の高さは納得できる。

また、風速計をいくつか調べてみると、その仕様は風速の分解能は高いが測定可能最低風速は高めな傾向があった。
今回の取得データと同じ傾向であり、納得できる。
tempの補正式取得
各月に於けるtempの分布
tempは負の値を取らないように補正されている模様。
実際の天気予報と見比べ、どのような補正がされているのか検証する。
なるべく広い温度域での分布を見たいので、各月のtempが分布を確認する。
sns.scatterplot(data=df_all, x="month",y="temp",hue = "year")

これをみると、2011年1月、2011年3月、2012年7月の3つの月を見るとtempの最大値、最小値、その間の数値と幅広く取得できそう。
この各月に対して、日付についてのtempの分布を見る。
#----check which day records lowest or highest temp---
fig,(axe1,axe2,axe3) = plt.subplots(1,3,figsize=(24,6))
axe1=sns.scatterplot(data= df_all[(df_all["year"]==2011) & (df_all["month"]==1)], x="day", y="temp",ax=axe1)
axe2=sns.scatterplot(data= df_all[(df_all["year"]==2011) & (df_all["month"]==3)], x="day", y="temp",ax=axe2)
axe3=sns.scatterplot(data= df_all[(df_all["year"]==2012) & (df_all["month"]==7)], x="day", y="temp",ax=axe3)
axe1.set_title("temp vs day in Jan 2011")
axe2.set_title("temp vs day in Mar 2011")
axe3.set_title("temp vs day in Jul 2012")
axe1.set_ylim(0,45)
axe2.set_ylim(0,45)
axe3.set_ylim(0,45)
plt.savefig("temp_vs_day_at_interested_month.png")
plt.show()
#====result : 23th.Jan.2011, 2nd.Mar.2011 and 7th.Jul.2012 are the interested days=====

良さそうな日をピックアップ。
2011年1月22日、2011年3月2日、2012年7月7日のデータを使用して確認する。
(※2011年1月23日が最低気温をマークしている中で最もtempの幅が広いが、実際の天気予報にはデータが1時52分の1サンプルのみしか記録されていなかった)
再度webから天気予報の表を取得してKaggleで読み込む。
(https://www.timeanddate.com/weather/usa/washington-dc/historic?month=7&year=2012 など、各年月日に対応する表を取得してKaggleにinputした)
取得したwebからのデータとKaggleのデータとを比較。
webからの取得データは欠損が点在しているのでKaggleのデータの当該箇所を削除して形を整える。
これをプロットすると、Kaggleのデータではtempが0未満にならないこと、実気温(webから取得)の最大値(41度)ではKaggleのデータでも同じ値を示す(41度)ことが分かる。
単純に、「負にならないように、且つ最大値は同じ値を示すように」というスケール変換を行っている模様。
パッと思い浮かぶ単純な式は以下。
t_{modified} = \frac{t - t_{min}}{t_{max}-t_{min}}*t_{max}
「負にならないように最小値を引く」「取り得る範囲で割り算して値を[0~1]の間にする」「最大値を掛けることで[0~最大値]を値の取り得る範囲にする」というイメージ。
実際の値と理論式による値との最小二乗法でフィッティングして理論式の妥当性を見たい。
これにはscipy.optimizeのcurve_fitを用いてフィッティングした。
天気予報データの取得、行数を合わせるために削除、散布図描画、フィッティングまで一度に記載する。
#load data from weather erport. https://www.timeanddate.com/weather/usa/washington-dc/historic?month=7&year=2012, etc.
#-----df for 22nd.Jan.2011, 2nd.Mar.2011 and 7th.Jul.2012 ------------

def html_to_df(filename):
    df_list = pd.read_html(filename)
    df = df_list[0]
    #columns are multi-index column. remove level 0.
    df.columns=[col[1] for col in df.columns]
    df = df[["Time","Temp","Weather","Wind","Humidity"]]
    return df
filename = ["/kaggle/input/weather-report-from-web/Extraction_Weather_22_Jan_2011.html",
            "/kaggle/input/weather-report-from-web/Extraction_Weather_2_Mar_2011.html",
            "/kaggle/input/weather-report-from-web/Extraction_Weather_7_Jul_2011.html"]
df_weather_Jan = html_to_df(filename[0])
df_weather_Mar = html_to_df(filename[1])
df_weather_Jul = html_to_df(filename[2])

#delete the unwanted string in end of line
df_weather_Jan = df_weather_Jan.drop(index=13,axis=0)
df_weather_Mar = df_weather_Mar.drop(index=15,axis=0)
df_weather_Jul = df_weather_Jul.drop(index=24,axis=0)

df_tmp_Jan = df_all[(df_all["year"] == 2011) & (df_all["month"] == 1) & (df_all["day"] == 22)][["hour","temp","weather","windspeed","humidity"]].reset_index(drop=True)
df_tmp_Mar = df_all[(df_all["year"] == 2011) & (df_all["month"] == 3) & (df_all["day"] == 2)][["hour","temp","weather","windspeed","humidity"]].reset_index(drop=True)
df_tmp_Jul = df_all[(df_all["year"] == 2012) & (df_all["month"] == 7) & (df_all["day"] == 7)][["hour","temp","weather","windspeed","humidity"]].reset_index(drop=True)

#----------display 3 weather report and 3 original data-----------
#for diplaying some dfs in tile holizontally. "n" means .head()
def display_horizon(*dfs, n=5):
    class HorizontalDisplay:
        def _repr_html_(self):
            template = '<div style="float: left; padding: 5px;">{}</div>'
            return  ''.join(template.format(df.head(n)._repr_html_()) for df in dfs)
    return HorizontalDisplay()

#---delete the row which is missing in weather report data--
drop_list_org_Jan = [0,2,3,4,6,9,17,18,19,20]
drop_list_org_Mar = [0,6,9,11,13,14,15,16,18,22]
drop_list_org_Jul = []
drop_list_weather_Mar=[14]

df_tmp_Jan = df_tmp_Jan.drop(index = drop_list_org_Jan, axis=0)
df_tmp_Mar = df_tmp_Mar.drop(index = drop_list_org_Mar,axis=0)
df_tmp_Jul = df_tmp_Jul.drop(index = drop_list_org_Jul,axis=0)
df_weather_Mar = df_weather_Mar.drop(index = drop_list_weather_Mar,axis=0)

print("="*30 + "comparison weather report and Kaggle data(some rows have been deleted)." + "="*30)
display(display_horizon(df_weather_Jan, df_tmp_Jan, n=25))
display(display_horizon(df_weather_Mar, df_tmp_Mar, n=25))
display(display_horizon(df_weather_Jul, df_tmp_Jul, n=25))


print("="*30 + "try fittin row temp as t by temp with some parameters" + "="*30)
df_tmp = pd.concat([df_tmp_Jan, df_tmp_Mar, df_tmp_Jul], ignore_index=True)
df_weather = pd.concat([df_weather_Jan,df_weather_Mar,df_weather_Jul], ignore_index=True)
df_weather["Temp"] = df_weather["Temp"].str.extract(r"(-?\d+)", expand=False).astype(float)

#scatter plot
sns.scatterplot(x= df_weather["Temp"], y = df_tmp["temp"])
plt.xlim(-10,45)
plt.ylim(-1,45)
#At first, draw just the scatter. at a glance, the theoritical curve can be assumed.
#Now draw the fitted curve.
#the prediction is raised that the data might be as the minmum temp must be >=0 and maximum temp should be equal to Temp from weather report.
#so the curve can be defined by (t - tmin) /(tmax - tmin) * tmax.
x_min = np.min(df_weather["Temp"].min())-1
x_max = np.max(df_weather["Temp"].max())+1
fx=np.linspace(x_min, x_max, 511)

#fitting function
from scipy.optimize import curve_fit
import sklearn.metrics as metrics

def func(x, x_min, x_max):
    y = (x - x_min) * x_max / (x_max - x_min)
    return y

param, cov = curve_fit(func, df_weather["Temp"].to_numpy().astype(float), df_tmp["temp"].to_numpy(), p0=[-9,41])
plt.plot(fx,(fx - param[0]) * param[1] / (param[1] - param[0]) ,color="r", linestyle="--")
r2 = metrics.r2_score(df_tmp["temp"], func(df_weather["Temp"] , param[0] , param[1]))
plt.annotate(f"fit : (t - tmin) / (tmax - tmin) * tmax \n where tmin:{param[0]}, tmax:{param[1]} \n R2 : {r2:.3f}", xy=(0.1, 0.75), xycoords="axes fraction", color = "r", fontsize=10)
plt.title("temp vs actual Temperature, fiited")
plt.savefig("temp_vs_actual_Temp_fit.png")
plt.show()

横軸は天気予報から得た実際の値(Temp)。縦軸はKaggleの「temp」。
結果、tempは実温度$t$、その最大値、最小値をそれぞれ$t_{max}$、$t_{min}$として、
temp = \frac{t - t_{min}}{t_{max}-t_{min}} * t_{max}
という算出と言える。
Kaggleの公式データの説明を探していくと $temp = \frac{t-t_{min}}{t_{max} - t_{min}}$ と書かれていたが正しくなかったようだ。
これより真のatemp推定のベースが得られ、外れ値を正確に修正することができると思われる。
humidity = 0 について
humidity = 0 のデータ確認
[humidity==0]を満たすデータを表示してみる。2011年3月10日で全てhumidity=0であった。
display(df_all[df_all["humidity"]==0])

この日はうまくデータ取得ができていなかったものと思われる。
事実上の欠損値がhumidity==0として記録されているのである。
データを用意したホストが.fillna(0)相当の処理をしてデータを公開したのかもしれない。
実際の天気予報を確認
実際の天気予報で当該日(2011年3月10日)の湿度を確認する。

いくつか欠損している時刻はあるが、湿度はほぼ100%の日であった。
欠損時刻の前後も長い時刻に亘り100%なので欠損時刻の湿度も100%で埋めればよさそう。
humidity = 0 を置換
#download the html
def html_to_df(filename):
    df_list = pd.read_html(filename)
    df = df_list[0]
    #columns are multi-index column. remove level 0.
    df.columns=[col[1] for col in df.columns]
    df = df[["Time","Temp","Weather","Wind","Humidity"]]
    return df

def display_horizon(*dfs, n=5):
    class HorizontalDisplay:
        def _repr_html_(self):
            template = '<div style="float: left; padding: 5px;">{}</div>'
            return  ''.join(template.format(df.head(n)._repr_html_()) for df in dfs)
    return HorizontalDisplay()


filename = "/kaggle/input/weather-report-from-web/Extraction_Weather_10_Mar_2011_DataOfHumid0.html"
df_weather_humid0 = html_to_df(filename)
df_weather_humid0 = df_weather_humid0.drop(index=20)

display(display_horizon(df_weather_humid0, df_all[(df_all["year"]==2011) & (df_all["month"] ==3) &(df_all["day"]==10)][["datetime","temp","windspeed","humidity"]], n=23))

import datetime as dt
df_weather_humid0["Time"] = pd.to_datetime(df_weather_humid0["Time"]).dt.round("h").dt.hour.astype(int)
df_weather_humid0=df_weather_humid0.drop(index=[9,14,19])
df_weather_humid0["Humidity"]=df_weather_humid0["Humidity"].str.extract(r"(-?\d+)",expand=False).astype(int)

def insert_df_middle_row(idx, df_orig, df_insert):
    if idx==0:
        return pd.concat([df_insert, df_orig], axis=0).reset_index(drop=True)
    else:
        return pd.concat([df_orig[:idx], df_insert, df_orig[idx:]], axis=0).reset_index(drop=True)

#creating DataFrame for insert missing time, as name df_insert
insert_base = np.zeros(df_weather_humid0.shape)
df_insert = pd.DataFrame(insert_base, columns=df_weather_humid0.columns)
missing_time = [0,6,7,9,10,11,13]
for i,val in enumerate(missing_time):
    df_insert["Time"].iloc[i] = val
df_insert = df_insert.drop(index = range(i+1,df_insert.shape[0]))

#search missing time on each row and insert the time.
for i, t1 in zip(df_insert.index,df_insert["Time"]):
    if t1 in df_weather_humid0["Time"].values:
        continue
    else:
        for j, t2 in zip(df_weather_humid0.index, df_weather_humid0["Time"]):
            if t1<t2:
                df_weather_humid0=insert_df_middle_row(j, df_weather_humid0, df_insert.iloc[i:i+1])
                break

#Fill in the humidity into the inserted time
df_weather_humid0.loc[0,"Humidity"] = 96
df_weather_humid0["Humidity"].mask(df_weather_humid0["Humidity"]==0,100, inplace=True)

#now replace the df_all["humidity"]==0.
for t1 in df_all.query("year == 2011 & month == 3 & day == 10")["hour"].values:
    for t2, humid in zip(df_weather_humid0["Time"],df_weather_humid0["Humidity"]):
        if t1 == t2:
            df_all["humidity"][ (df_all["year"]==2011) & (df_all["month"]==3) & (df_all["day"]==10) & (df_all["hour"]==t1)] = humid
            break
display(df_all.query("year==2011 & month==3 and day==10"))

事実上の欠損値であったhumidity = 0を埋めた。
tとhumidity、windspeedからatを算出
atemp・tempとhumidity・windspeedの関係
atempの外れ値:12.12
再度散布図プロットする。横軸をtemp、縦軸をatempとする。
import matplotlib.patches as patches
axe=sns.scatterplot(data=df_all , x="temp", y= "atemp" )
plt.axis("square")
#add line of y=x
plt.axline((0, 0), slope=1, color='red', lw=1)
e = patches.Ellipse(xy=(30,12), width = 15, height=4 , fill=False, ec="r")
axe.add_patch(e)
axe.annotate("outlier", xy=(30,16), color="r")
plt.title("atemp vs temp, scatter")
plt.savefig("atemp_vs_temp_scatter.png")
plt.show()

temp = atemp であった場合の直線を赤で追加している。
また、temp=25度~35度かつatemp=12度あたりに外れ値がある。
この外れ値になっているところを赤く丸で囲っている
当該エリア、temp=25度~35度近辺、atemp=12度あたりのデータを見てみる。
# check area of outlier points!
display(df_all[(df_all["temp"] > 20) & (df_all["atemp"] < 15)])

よく見ると日付が2012年8月17日にて、0時~23時まですべてatemp値=12.12となっている。
恐らくレンタル自転車の自動計測システムのエラーでこの日は値が取得できず、同一値を記録してしまったか、他の理由で誤って数値が同一の値に書き換わったかかと推測される(追って確認・考察記載)。
2012年8月17日に於けるatempは削除するか、tempやhumidityなどから予測するか、または説明変数atempは用いないかの選択がある。
今回は計算で求められそうなので、temp、humidity、windspeedの値を用いて計算する。
humidity, windspeedとatempの関係
atempとtempについて描画したプロットに対し、以下の色分けをする。
- humidityの値で色分け
- windspeedの値で色分け
#=====next, plot the one with humidity and windspeed、by color-coded.======
fig, axes = plt.subplots(1,2,figsize=(15,6))
hue_list = ["windspeed", "humidity"]
for i, axe in enumerate(axes):
        sns.scatterplot(data=df_all, x="temp", y="atemp", hue = hue_list[i],ax=axe)
        axe.set_title("atemp vs temp, colored by " + hue_list[i])
s0 = patches.Rectangle(xy=(0,-1), width = 15,height =21, fill=False,ec="r",linestyle="--" )
s1 = patches.Rectangle(xy=(24,24), width = 18,height =28, fill=False,ec="r",linestyle="--" )
axes[0].add_patch(s0)
axes[1].add_patch(s1)
plt.suptitle("atemp vs temp, colored by windspeed and humidity")
plt.savefig("atemp_vs_temp_colored_by_windspeed_and_humidity.png")
plt.show()

赤点線で囲った個所に注目。
低温度域ではwindspeedに依りatempは低下、高温度域ではhumidityに依り上昇(一部では低下)している。
この関係を調べる。
tempを真の温度値t[℃]に逆変換する。
真の温度値は、 $t = \frac{50}{41} * temp -9$ より求められることが前節で分かっている。
(具体値、$t_{max} = 41, t_{min} = -9$ を代入した)
#=====plot the one, by raw temperature "t"======
df_tmp = df_all[["temp", "atemp", "humidity", "windspeed"]]
df_tmp["t"] = df_tmp["temp"]*50/41-9

fig, axes = plt.subplots(1,2,figsize=(15,6))
hue_list = ["windspeed", "humidity"]
for i, axe in enumerate(axes):
        sns.scatterplot(data=df_tmp, x="t", y="atemp", hue = hue_list[i],ax=axe)
        axe.set_title("atemp vs actual temp t, colored by " + hue_list[i])
plt.title("atemp vs actual_temperature 't'")
plt.savefig("atemp_vs_acttual_t_colored_by_windspeed_and_humidity.png")
plt.show()
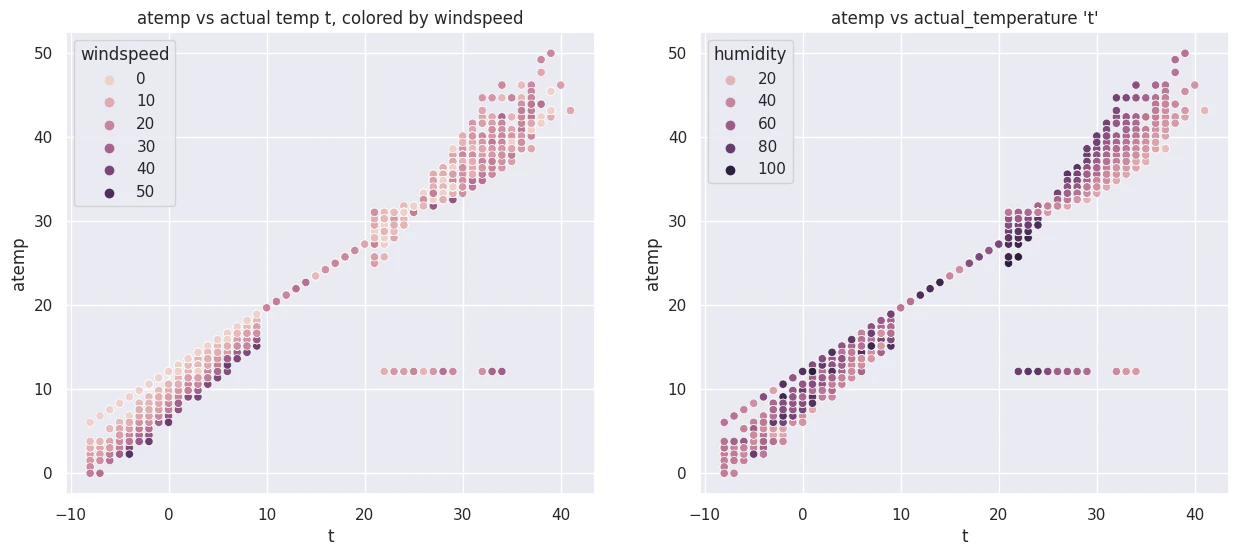
以下が分かる
| 温度域 | 分類 |
|---|---|
| $t \lt 10℃$ | windspeedに依存 |
| $10℃ \leqq t \leqq 20℃$ | 依存なし |
| $20℃ \leqq t$ | humidityに依存 |
俗に、体感温度について高温域で湿度が支配的な因子、低温域で風速が支配的な因子とされており経験則と合致する。
各温度域で調べてみる。
高温域:湿度依存:Heat Index
NWS(National Weather Service)のHPより、「Heat Index」の説明文を取得。
https://www.wpc.ncep.noaa.gov/html/heatindex_equation.shtml

気温20度以上に対してHeat Indexを計算してプロットする。
NWSでは特定の湿度域と温度域を3つ設け、該当する場合には補正項を与えることで正確な値(湿度による体感温度の逆転のない分布)を作成している。
Kaggleでのatempはこの補正項を採用していない値のようで、補正なしの計算結果とatempの分布とがよく一致する。
#========NWS (National Weather Service)=============#
#---heat index:
def HeatIndex(t, h):
    F = t*1.8 + 32
    HI = -42.379 + 2.04901523*F + 10.14333127*h \
        -0.22475541*F*h - 0.00683783*F**2 - 0.05481717*h**2 \
        +0.00122874*F**2*h + 0.00085282*F*h**2 \
        - 0.00000199*F**2*h**2

#Adjustment factor : humid is too low or humid is extremely high or temp is extlemely high or
#    if( (h<13) & (80<=F<=112) ):
#        HI = HI - (13-h)/4*np.sqrt( (17 - np.abs(F - 95)) /17)
#    elif( (h>85) & (80<=F<=87) ):
#        HI = HI + (h - 85) * (87-F)/50
#    elif(F<80 ):
#        HI = 0.5*(F + 61) + 0.6*(F - 68) + 0.047 * h
    HI_Celsius = (HI -32 / 1.8)

    return HI_Celsius

df_tmp_high = df_tmp[df_tmp["t"]>20]
df_tmp_high = df_tmp_high.reset_index(drop=True)
HI = []
for t,h in zip(df_tmp_high["t"], df_tmp_high["humidity"]):
    HI.append(HeatIndex(t,h))

df_tmp_high = pd.concat([df_tmp_high, pd.Series(HI,name="HeatIndex")],axis=1)
display(df_tmp_high)
fig ,axes = plt.subplots(1,2,figsize = (15,6))
axes[0] = sns.scatterplot(data=df_tmp_high, x="t", y="HeatIndex",hue = "humidity", ax=axes[0])
axes[1] = sns.scatterplot(data=df_tmp[(df_tmp["t"]>20) & (df_tmp["atemp"] !=12.12)], x="t",y="atemp", hue="humidity",ax=axes[1])
axes[0].set_tile("calculated atemp, by HeatIndex")
axes[1].set_title("original atemp, 12.12 are removed")
plt.show()

縦軸の絶対値が合わないのは、atemp値はマイナスの値を取らないように真の値に対して補正をしているため(tempと同じ状況と思われる)。
散布図を改めてみると、atemp分布に対する湿度は25度を境界に逆転している。
(25度以上で湿度上昇に伴いatemp上昇、25度以下で湿度上昇に対しatemp減少)
また、25度から20度に向かうにつればらつきが増大している。
これはNWSの示す「補正項」を導入していない故である。
実際に補正項も導入して計算すると以下のように逆転はなくなり、また25度から20度へ向かう際のばらつきが小さくなって実体感に即した分布となる。
#========NWS (National Weather Service)=============#
#---heat index:
def HeatIndex(t, h):
    F = t*1.8 + 32
    HI = -42.379 + 2.04901523*F + 10.14333127*h \
        -0.22475541*F*h - 0.00683783*F**2 - 0.05481717*h**2 \
        +0.00122874*F**2*h + 0.00085282*F*h**2 \
        - 0.00000199*F**2*h**2

#Adjustment factor : humid is too low or humid is extremely high or temp is extlemely high or
    if( (h<13) & (80<=F<=112) ):
        HI = HI - (13-h)/4*np.sqrt( (17 - np.abs(F - 95)) /17)
    elif( (h>85) & (80<=F<=87) ):
        HI = HI + (h - 85) * (87-F)/50
    elif(F<80 ):
        HI = 0.5*(F + 61) + 0.6*(F - 68) + 0.047 * h

    HI_Celsius = (HI -32 / 1.8)

    return HI_Celsius

df_tmp_high = df_tmp[df_tmp["t"]>20]
df_tmp_high = df_tmp_high.reset_index(drop=True)
HI = []
for t,h in zip(df_tmp_high["t"], df_tmp_high["humidity"]):
    HI.append(HeatIndex(t,h))

df_tmp_high = pd.concat([df_tmp_high, pd.Series(HI,name="HeatIndex")],axis=1)
display(df_tmp_high)
fig ,axes = plt.subplots(1,2,figsize = (15,6))
axes[0] = sns.scatterplot(data=df_tmp_high, x="t", y="HeatIndex",hue = "humidity", ax=axes[0])
axes[1] = sns.scatterplot(data=df_tmp[(df_tmp["t"]>20) & (df_tmp["atemp"] !=12.12)], x="t",y="atemp", hue="humidity",ax=axes[1])
axes[0].set_title("calculated atemp, by HeatIndex")
axes[1].set_title("original atemp, 12.12 are removed")
plt.show()

レンタル自転車利用者は補正項付きの体感温度に即した動向を示すと考えられ、レンタル自転車利用者数の予測には補正項付きの体感温度(Heat Index)値を使用するべきと考える。
低温域:風速依存:Wind Chill
NWSより、Wind Chillも同様に取得。
https://www.weather.gov/safety/cold-wind-chill-chart

これから低温域側のatempを計算してみる。
ただし、Wind Chill値は風速3mph(≒4.83km/h)以上で有効(これ以下では計算上逆に体感温度が上がるという逆転を起こす)。
持っているデータ「windspeed」では、0の次に大きな風速は6.0032km/hなので、windspeed=0を計算から除外すればよい。
#==========NWS windchill==============
#in low temp area, t<10 deg.C
def wind_chill(t, w):
    if w == 0:
        return t
    else:
        F = t * 1.8 + 32
        mph = w *0.621371
        WC = 35.74 + 0.6215*F -35.75 * mph**0.16 + 0.4275*F*mph**0.16
        WC_Celsius = (WC - 32) / 1.8

        return WC_Celsius

df_tmp = df_all[["temp", "atemp", "humidity", "windspeed"]]
df_tmp["t"] = df_tmp["temp"]*50/41-9

df_tmp_low = df_tmp[df_tmp["t"]<10]
df_tmp_low = df_tmp_low.reset_index(drop=True)

WC = []
for t,w in zip(df_tmp_low["t"], df_tmp_low["windspeed"]):
    WC.append(wind_chill(t,w))

df_tmp_low = pd.concat([df_tmp_low, pd.Series(WC,name="WindChill")],axis=1)
display(df_tmp_low)
fig ,axes = plt.subplots(1,2,figsize = (15,6))
axes[0] = sns.scatterplot(data=df_tmp_low, x="t", y="WindChill",hue = "windspeed", ax=axes[0])
axes[1] = sns.scatterplot(data=df_tmp[(df_tmp["t"]<10) & (df_tmp["atemp"] !=12.12)], x="t",y="atemp", hue="windspeed",ax=axes[1])
axes[0].set_title("calculated atemp, by Wind Chill")
axes[1].set_title("original atemp, 12.12 are removed")
plt.savefig("windchill.png")
plt.show()

中温度域:直線領域
基本となる直線。
ここでは特にwindspeedやhumidityの値に依らない。tempのみに依存する直線であることが分かる。
よって、割愛して次の章に行く。
tとatemp
atemp=12.12と、atempの補正式
import sklearn.metrics as metrics
from scipy.optimize import curve_fit

df_tmp = df_all
df_tmp["t"] = 50/41*df_tmp["temp"] - 9
df_tmp=df_tmp.query("10<=t<=20")

#fit by numpy_polyfit, by 1st order
coef = np.polyfit(df_tmp["t"], df_tmp["atemp"], 1)
print(coef)
r2_polyfit = metrics.r2_score(df_tmp['atemp'], df_tmp['t']*coef[0]+coef[1])
print(f"r2 score : {r2_polyfit}")

#fut by scipy.optimize.curve_fit, with parameter t_min, t_max
def func(t, min, max):
    y = (t - min) * max / (max - min)
    return y
param, cov = curve_fit(func, df_tmp["t"].to_numpy().astype(float), df_tmp["atemp"].to_numpy().astype(float), p0 = (-15.7,50.3))
print(param)
r2_paramfit = metrics.r2_score(df_tmp['atemp'], func(df_tmp['t'],param[0],param[1]))
print(f"r2 score : {r2_paramfit}")

fig, (axe1,axe2) = plt.subplots(1,2,figsize=(15,6),sharex=True, sharey=True)
axe1=sns.scatterplot(data=df_tmp, x="t",y="atemp",ax=axe1)
axe2=sns.scatterplot(data=df_tmp, x="t", y ="atemp" ,ax=axe2)
axe2.axline( (10,(10 - param[0]) * param[1] / (param[1] - param[0])), (20,(20 - param[0]) * param[1] / (param[1] - param[0])) ,color="r", linestyle="--")
axe1.set_xlim(9,21)
axe1.set_ylim(18,30)
axe1.axline((0,coef[1]),slope= coef[0],color="r", linestyle="--")
axe1.annotate(f"fit line : \ny={coef[0]:.3f}*t + {coef[1]:.3f} \nR2_score : {r2_polyfit:.3f}",xy=(0.1,0.75),xycoords='axes fraction', color="r")
axe1.set_title("atemp vs actual t, with polyfit")
axe2.annotate(f"fit line : y=(t-t_min)/(t_max - t_min) * t_max \n where t_min = {param[0]:.3f}, t_max = {param[1]:.3f} \nR2_score : {r2_paramfit:.3f}",xy=(0.1,0.75),xycoords='axes fraction', color="r")
axe2.set_title("actual apparent temperature vs actual t, with parameter fit")
axe2.yaxis.set_tick_params(labelleft=True)
plt.suptitle("atemp vs actual temperature t")
plt.show()

atempの外れ値に「12.12」があったが、これは「atemp vs t」の切片の値であった。
つまり温度tの入力がない場合に得られるatempの値が「12.12」ということである。
atemp=12.12は、外れ値というより欠損値であったことが分かる。
また、真の体感温度値atをatempの値へ変換する式は、真の体感温度atの最大値と最小値を用いて以下のように表される。
atemp = \frac{at - at_{min}}{at_{max}-at_{min}} * at_{max}
| at | 真の体感温度値[℃] |
| at_{min} | 真の体感温度の最小値[℃] |
| at_{max} | 真の体感温度の最大値[℃] |
正しいatempを算出
これまでの知見より、atは真の温度tから算出され、3つの温度範囲t1, t2, t3で補正の有無が異なることを得た。
| $t1 : t \lt 10℃$ | Wind Chillによる補正 |
| $t2 : 10 ℃ \leqq t \leqq20 ℃$ | 補正なし |
| $t3 : t \gt 20$ | Heat Index による補正 |
| atemp | tからatを計算し、負の値を避けるために補正して得る |
実際にこれらの演算により正しいatemp値を取得する。
名前はat_normとする。
# run the cell fill thehumidity == 0 beforehand.
display(df_all)
if df_all[df_all["humidity"]==0].empty:
    print("Good, 'humidity == 0' has already been filled in.")
else:
    print("Please run the cell , fill humidity == 0 before hand.")
    sys.exit()

df_all["t"] = df_all["temp"]*50/41-9

#Define functions for windchill and heat index.
def select_case_and_call_calc(t,w,h):
    if t < 10:
        return wind_chill(t,w)
    elif t >20:
        return HeatIndex(t,h)
    else:
        return t

#Calculate Wind Chill, in case t<10
def wind_chill(t, w):
    if w == 0:
        return t
    else:
        F = celsius_to_F(t)
        mph = w *0.621371
        WC = 35.74 + 0.6215*F -35.75 * mph**0.16 + 0.4275*F*mph**0.16
        WC_Celsius = F_to_celsius(WC)
        return WC_Celsius

#Calculate Heat Index, in case t<20
def HeatIndex(t, h):
    F = celsius_to_F(t)
    HI = -42.379 + 2.04901523*F + 10.14333127*h \
        -0.22475541*F*h - 0.00683783*F**2 - 0.05481717*h**2 \
        +0.00122874*F**2*h + 0.00085282*F*h**2 \
        - 0.00000199*F**2*h**2
    #Adjustment factor : humid is too low or humid is extremely high or temp is extlemely high or
    if( (h<13) & (80<=F<=112) ):
        HI = HI - (13-h)/4*np.sqrt( (17 - np.abs(F - 95)) /17)
    elif( (h>85) & (80<=F<=87) ):
        HI = HI + (h - 85) * (87-F)/50
    elif(F<80 ):
        HI = 0.5*(F + 61) + 0.6*(F - 68) + 0.047 * h
    HI_Celsius = F_to_celsius(HI)
    return HI_Celsius

def celsius_to_F(t):
    return t*1.8+32.0
def F_to_celsius(F):
    return (F-32.0)/1.8

at_list=[]
#Calculate Windchill ,Heat Index on each row.
for t, w, h in zip(df_all["t"], df_all["windspeed"], df_all["humidity"]):
    at_list.append(select_case_and_call_calc(t,w,h))

#previously retlieved the coefficient for normalize at into at_norm.
at_min = -15.989
at_max = 50.035

at_list = np.array(at_list, dtype=float)
df_all["at"] = pd.Series(at_list,name="at")
at_list = (at_list - at_min) * at_max / (at_max - at_min)
df_all["at_norm"] = pd.Series(at_list,name="at_norm")

fig ,(axe1,axe2) = plt.subplots(1,2,figsize=(15,6))
axe1 = sns.scatterplot(data=df_all,x="temp",y="atemp",ax=axe1)
axe2 = sns.scatterplot(data=df_all,x="temp",y="at_norm",ax=axe2)
axe1.set_title("Original atemp vs temp")
axe2.set_title("calculated atemp, 'at_norm' vs temp")
plt.suptitle("check calculated atemp named at_norm")
plt.savefig("Check_calculated_atemp.png")
plt.show()

fig ,axes = plt.subplots(2,2,figsize=(15,15))
name_list=["atemp","at_norm","humidity","windspeed"]
for i,ax in enumerate(axes.ravel()):
    ax = sns.scatterplot(data=df_all,x=name_list[i//2+2],y=name_list[i%2],ax=ax)
    ax.set_title(f"{name_list[i%2]} vs {name_list[i//2+2]}")
plt.suptitle("distribution of atemp and at_norm against humidity and windspeed")
plt.show()
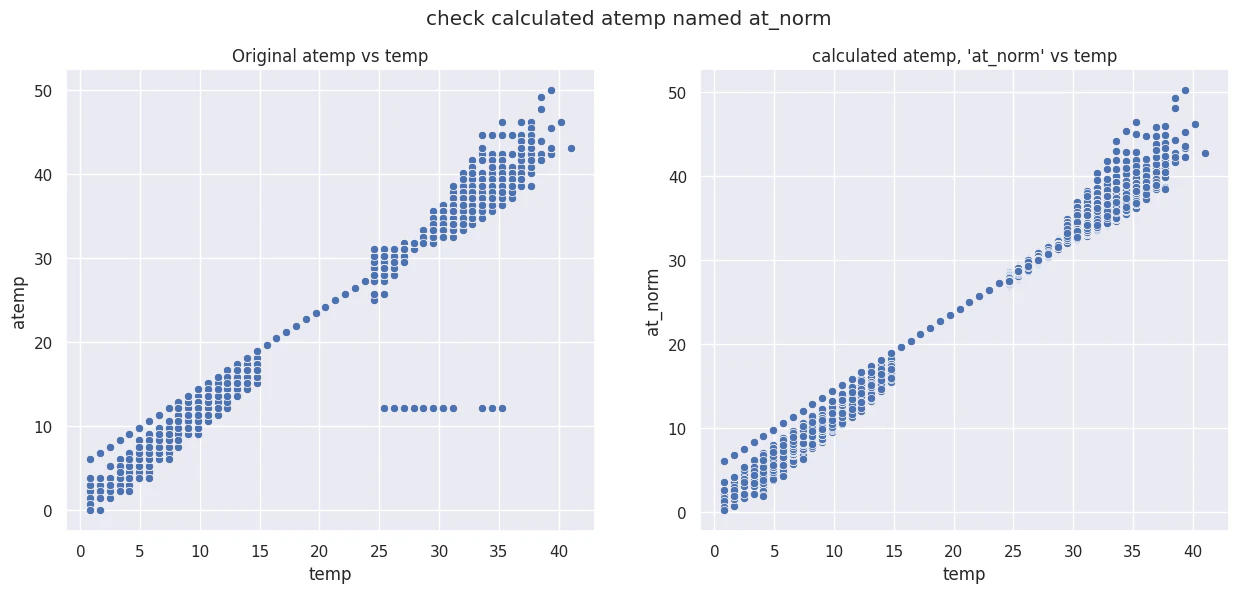

これにより正しいatempが算出できた(at_normと命名)。
Heat Indexに正しい補正を導入したので、temp=28℃付近で見られる湿度に対する折り返しや24℃付近の不連続点が改善されている。
humidityに対する体感温度(atemp、at_normの2種類)の散布図を比較すると歪みがなくなっているのが分かる。
一方、windsppedに対する歪は解消できない。
これは体感温度を算出するWind Chill値が風速約4.83m/h以上で定義されていること、また、そもそも風速が6km/h未満のものはセンシングされていないようで全て0にカウントされていることにより補正はできない。
加えて、事実上欠損値であった「atemp=12.12」も計算により正しく値が代入された。
途中で「humidity=0」という事実上の欠損値も正しい値を取得して補完している。
最後に
本稿に関するまとめ。
- webより天気予報の情報を取得
- 天気予報とKaggleのデータを見比べて編集
- tempの補正式を予想、妥当性確認、真の温度tを算出
- atemp(体感温度)はNWSに計算方法が記載されていた
- 温度、湿度、風速より体感温度を算出
- 各温度域で、真の温度tより真の体感温度atを正しく算出できることを確認
- 真の体感温度atをatempに直す補正式を予測、妥当性確認
- 上記一連の情報・演算より、真の体感温度をatempと同じ形式にノーマライズした「at_norm」を得た
- 途中、外れ値であるhumidity=0、atemp=12.12は補完された
それぞれ難しい内容はなかったが、Pythonに不慣れなため膨大な時間がかかった。
データ分析方法や演算方法など、アイデアは無数に浮かぶが実装に時間がかかる。
今回の試行錯誤でかなりPythonや周辺のデータ分析ライブラリに関して学んだ。
計算、フィッティングについて。Heat Index、windspeedはNWSが式を開示していたので助かった。
当初の予想よりも複雑な式であり、且つ国によって採用している体感温度の計算手法が異なっており、
ワシントンD.C.於ける体感温度の算出はNWSに記述がなければ至難であった。
または、データの出自がWashington D.C.であるという情報が無かったら解に辿り着けなかったと思う。
humidity=0やatemp=12.12などの外れ値は、今回は天気予報情報の取得や計算で正しい値が導出できたため問題なかったが、
これらが使用できない場合には他の説明変数群から予測値を補完することになる。
この補完も目的変数の予測と同様に、機械学習アルゴリズムで行うことができると思われる。
こうした、欠損値の予測という問題も一度実施してみたい。
今後の課題とする。